Open to Summer 2026 internships and new graduate roles

OjasSuratkar.

AI/ML engineerbased in Los Angeles.

I train models and ship the systems around them: gradient boosted ensembles over hundreds of thousands of records, retrieval pipelines, and the services and interfaces that put them in front of people.

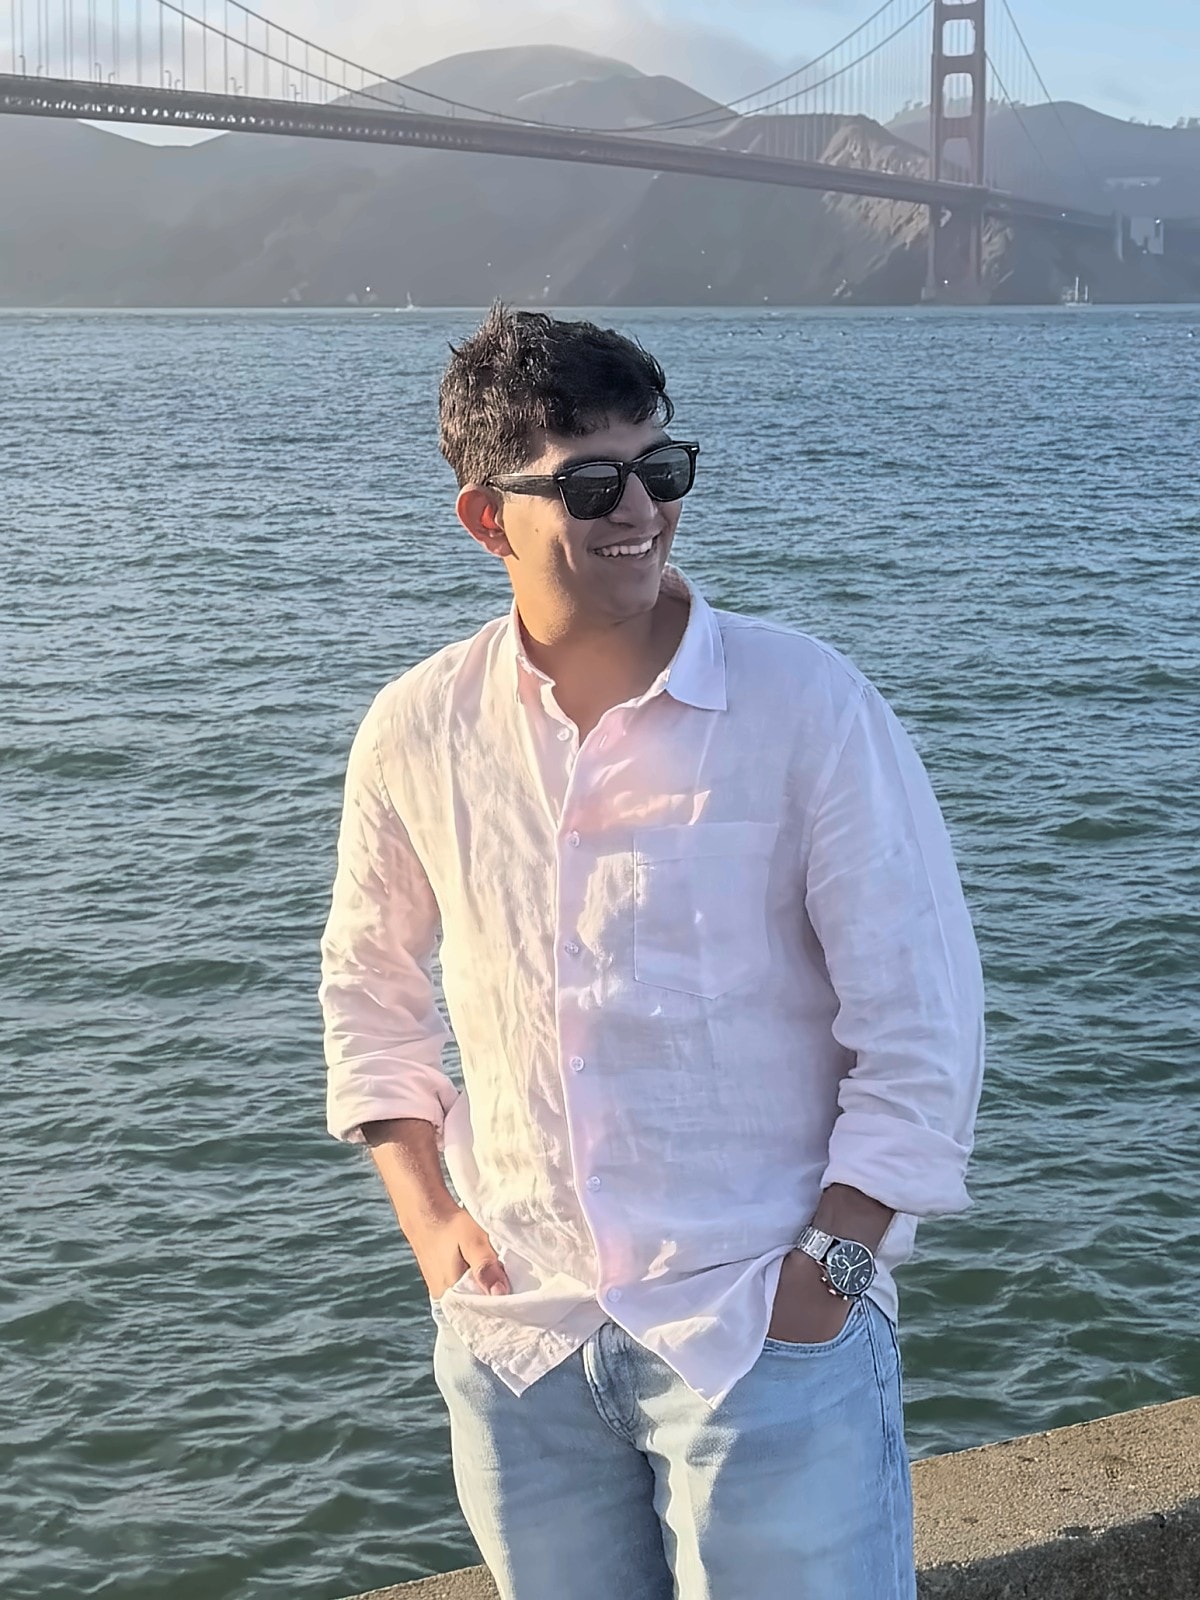
Portrait of Ojas Suratkar
  • 0%Faster university reporting, in production
  • 0%Lower latency on the NLP service I rebuilt
  • 0ML systems shipped end to end
  • 0.0GPA, MS Information Systems (AI/ML)

01 / About

Data in.Decisions out.

Based in
Los Angeles, CA
Studying
MS Information Systems, CSULB
Graduating
May 2027
Focus
ML, data science, full stack

I work across the whole ML workflow. I engineer features and train models on real data, gradient boosted ensembles, transformers and retrieval pipelines, then ship them behind FastAPI services and Next.js front ends where they have to hold up.

On the modelling side: an XGBoost ensemble over 440,000 container shipments that predicts port delay to within 1.36 days and flags detention risk at 92 percent accuracy, which won the EDRAY competition; a transformer summarisation service rebuilt to cut latency by 30 percent; and an econometric study estimated with fixed effects. On the engineering side those models ship, behind FastAPI services, typed schemas that reject a bad parse before it reaches the database, Terraform on GCP, and interfaces people actually use.

Currently

AI Engineer in Institutional Research & Analytics at CSULB, building the models and services behind institutional reporting on FastAPI, async SQLAlchemy, Next.js and Cloud Run.

Looking for

Roles in AI/ML and software engineering, data engineering, analytics and data science, and technical product work.

02 / Education

Foundation.

  • Expected May 20274.0/ 4.0 GPA

    M.S. Information Systems

    AI/ML track

    California State University, Long Beach

    • Database Management
    • Business Data Analytics
    • Machine Learning
    • Systems Analysis
  • Aug 2021 – May 20259.42/ 10 CGPA

    B.Tech Electronics & Telecommunication

    Specialization in AI

    Ramrao Adik Institute of Technology, D.Y. Patil University

  1. Sep 2025 – PresentCurrent

    AI Engineer

    Institutional Research & Analytics, CSULB

    • Designed and shipped the full stack platform that replaced manual transcript review: FastAPI microservices, a Next.js and TypeScript front end, Microsoft SSO with role based access control, and a normalised PostgreSQL schema on Cloud SQL, deployed to Cloud Run through GitLab CI/CD with pytest gates.
    • Built the AI layer: custom trained Google Document AI processors behind a multi agent LLM validation service (LangChain, CrewAI) and a rules engine that issues application decisions, on distributed asynchronous document processing.
    • Engineered Python, SQL and PySpark ETL pipelines on Databricks, orchestrated with Airflow and governed in Unity Catalog, and tuned the database with indexing and partitioning across 500,000+ applicant records, reducing reporting time 40 percent.
    • Developed an XGBoost model forecasting admission yield on 500,000+ records with Optuna tuning, cross validation, SHAP explainability and MLflow tracking, served to leadership in Tableau.
    • Led the delivery track as technical point of contact: user research, PRDs and user stories, backlog prioritisation in Jira, Agile ceremonies, weekly status reporting, and live demonstrations to leadership, peer universities and industry partners.

    40%less analyst time on recurring reports

  2. Sep 2025 – Dec 2025Campus

    Data Analytics Assistant

    College of Business, CSULB

    • Developed Python, SQL and PySpark pipelines in Databricks that ingest LMS gradebook exports into Delta Lake tables, with automated validation for duplicates, schema drift and missing values.
    • Designed star schema reporting models with dbt transformations, and built Tableau and Power BI dashboards on grade distributions, cohort analysis and scheduling KPIs.
    • Automated scheduled Databricks Workflows covering 2,000+ students across 100+ courses, cutting manual effort 35 percent at 100 percent accuracy.
    • Applied statistical tests to grade distributions and assessment outcomes, and partnered with the Dean on KPI definition, academic planning and resource allocation.

    35%less manual effort, at 100 percent accuracy

  3. Jan 2025 – May 2025Internship

    Machine Learning Engineering Intern

    D.Y. Patil University

    • Fine tuned BERT in PyTorch and Hugging Face for summarisation across PDFs, audio, video and web pages, reaching 0.42 ROUGE-L with 30 percent faster batched inference.
    • Implemented the core algorithms from scratch in Python with object oriented design: Smith-Waterman local alignment for source tracing, STFT audio fingerprinting for clip search, SHA-256 hash chains with Merkle proofs, and CRDTs for conflict free merges.
    • Designed the SQLAlchemy data model and Flask ingestion pipelines behind the product, and analysed model errors in Pandas to guide retraining.
    • Scoped the feature set from user needs and prioritised the trust features users asked for, so every summary traces back to its source passage.

    30%lower end to end latency

  4. Sep 2022 – Aug 2023Leadership

    AI/ML Facilitator

    Google Developer Student Clubs, RAIT

    • Designed and delivered workshops on supervised learning, model evaluation and Python development, each built around a worked problem rather than slides.
    • Created hands on coding exercises and problem sets so the chapter learned by building rather than watching.
    • Ran interactive group sessions that broke complex topics into simplified, example driven explanations.
    • Coordinated with technical, content and design leads on initiative planning, and contributed to solution strategy during the chapter's AI focused hackathon.

    100+engineers trained

04 / Projects

Builtto ship.

Seven builds across full stack platforms, applied ML and data analysis. Every one is on GitHub.

01Document pipeline and records platform, built at CSULB Institutional Research & Analytics · 2026GitHub

Transcript Hub

Problem

A high school transcript arrives as a scanned PDF and an admissions officer re-keys every course, grade and credit by hand, then it happens again at the next institution.

What I built

A platform that pulls the structured record out of the scan, verifies each requester with a one time code, and moves it through review across three roles.

How it works

Document AI reads the page with layout awareness, so a course table stays a table. The result is validated against a typed schema before any write, so a bad parse raises instead of landing in the database.

The pieces
  • ExtractionLayout aware OCR into a typed record, not loose text.
  • ValidationSchema check before persistence, so a bad parse fails loudly.
  • InfrastructureCloud SQL and Cloud Run in Terraform, Alembic migrations.
Why it is built this way

The hard part is not reading a transcript, it is trusting it: extraction proposes, the schema decides, and only then does anything persist.

  • FastAPI
  • PostgreSQL
  • React
  • TypeScript
  • Document AI
  • Terraform
Recording, records replaced

3roles on one audited record: student, school, reviewer

A transcript that used to be re-keyed by hand arrives as a validated record with its own verification trail.

02Data analysis, LMU Datathon · 2026GitHub

Wage Gap Insights

Problem

Pay gaps persist between people doing similar work, and setting pay from salary history carries an old gap into every job that follows.

What I built

A study over the NLSY97 job level panel, roughly 170,000 observations from 1997 to 2021, with model summaries and a policy counterfactual in a dashboard anyone can open.

How it works

Fixed effects estimated within job and industry, so the comparison holds the role constant rather than averaging a nurse against a trader, then a simulation of a salary history ban.

The pieces
  • Panel24 years of job level records cleaned to consistent fields.
  • EstimationJob and industry fixed effects: a 10.2 percent female penalty.
  • CounterfactualCalifornia’s 2018 salary history ban as the experiment.
  • DashboardChart.js, static, nothing to run to interrogate the result.
Why it is built this way

Headline gap figures compare across the labour market, which mixes the gap with how people are sorted into jobs. Holding job fixed answers the narrower and harder question.

  • Python
  • NLSY97 panel
  • Fixed effects
  • Chart.js
Screen recording

10.2%female wage penalty, fixed effects within job and industry

Women’s wage growth rose about 2 to 3 points after California’s 2018 salary history ban, with a residual gap still left.

03Document workspace, algorithms over a model. 1st Prize, IETE-RAIT Winternship · 2026GitHub

SummarEase

Problem

A chat assistant summarises a document and then forgets it. The source is gone, and nothing stays searchable across everything you have read.

What I built

A workspace that keeps the originals. Documents, recordings, video and web pages stay playable and searchable, with summaries beside them and analysis across the whole collection.

How it works

Nine modules implement published algorithms directly on stored text, so most of the product is deterministic rather than a model call.

The pieces
  • ProvenanceSmith-Waterman alignment with affine gaps, returning character offsets.
  • ChronologyA grammar parses dates out of text and orders every mention.
  • AudioSTFT fingerprinting locates a clip inside a long recording.
  • IntegritySHA-256 hash chain with Merkle proofs, CRDTs for merges.
Why it is built this way

A chat assistant summarises better, and the project says so. What it cannot do is keep your material, or name the passage a claim came from.

  • Python
  • Flask
  • SQLAlchemy
  • NumPy
  • scikit-learn
Screen recording

523passing checks across nine algorithm modules

Most of the app keeps working with no AI key configured, and the end to end suite proves it rather than claiming it.

04Supply chain operations · 2025, rebuilt 2026GitHub

InventiFlow

Problem

Vendors, production, warehouses and distributors each keep their own spreadsheet, so an order at one end tells nobody at the other what to make or buy.

What I built

Four role dashboards over one schema. A distributor order releases warehouse stock, a restock becomes a production run, and the run derives its raw materials from the product recipe, with SKU level demand forecasting and what if simulation on top.

How it works

Next.js over Supabase Postgres with row level security, on a schema rebuilt from the queries the app actually makes after the original database was lost.

The pieces
  • DistributorOrders from the warehouse that covers its postcode.
  • WarehouseAccepts against live stock and decrements in the same step.
  • ProductionDerives material needs from the recipe and flags shortfalls.
  • VendorFills the raw material requests that shortfall creates.
Why it is built this way

The dashboards are views onto one order trail rather than four applications, which is why a single order moves stock, opens a run and raises a purchase with nothing typed twice.

  • Next.js
  • TypeScript
  • Supabase
  • PostgreSQL
  • Python
  • XGBoost
  • Prophet
  • Databricks
Screen recording

35%better simulated demand and supply alignment, across four role dashboards

Stock, runs and material shortfalls all move from a single order, with nothing typed in twice.

05Transit app, geospatial ML · 2024, reworked 2026GitHub

MumBus

Problem

Riders cannot tell which bus serves their trip or how full it will be. The app that answered this had one city written into five screens as stop names, coordinates and routes.

What I built

A rider and conductor app that matches a bus to a start and end stop, follows it on a live map and predicts crowding by time slot. It now runs in any city.

How it works

Stops load from Supabase, then OpenStreetMap, then a snapshot. DBSCAN over haversine distance groups them into neighbourhoods, and lines chain through nearest neighbours.

The pieces
  • Line buildingClustering, then lines capped at a realistic stop count.
  • Trip planningBreadth first across the network, fewest changes, either direction.
  • RoutingOSRM through the backend, so no map key ships in the bundle.
  • CrowdingHistorical ridership per slot, plus live density within 50 m of a stop.
Why it is built this way

Moving the city into a data layer is what makes it a transit app rather than a Mumbai app: point CITY at Berlin and the lines rebuild from OpenStreetMap.

  • Python
  • FastAPI
  • Kafka
  • Spark Structured Streaming
  • scikit-learn
  • PostGIS
  • React Native
  • Mapbox
Screen recording

138Long Beach and Los Angeles stops served from one config line

Moving the app to a new city is one setting. Tables, routes and buses are seeded from live OpenStreetMap data.

06Learning platform with a career layer · 2024, rebuilt 2026GitHub

Career Matrix

Problem

Students take courses in one system and plan careers in another. Career advice stays generic and the skills on a resume are self reported.

What I built

A Canvas style LMS where every graded assignment is tagged with the skills it builds, so grades become an evidence backed profile matched against twelve career roles.

How it works

Mastery is level times confidence, where confidence rises with the weight of evidence behind it, so one lucky quiz cannot read as strong.

The pieces
  • Skill matrixGraded submissions become evidence, weighted by recency.
  • CopilotBM25 fused with Gemini embeddings by reciprocal rank fusion, cited.
  • IntegrityA request to solve open graded work switches it to coach mode.
  • PlannerEarliest deadline first, with overload flagged from slack.
Why it is built this way

Readiness is computed from graded work rather than self report, which is the argument of the project. Every AI feature has a deterministic fallback, and responses land near 20 ms where the first version chained five model calls.

  • Python
  • FastAPI
  • Next.js
  • TypeScript
  • PostgreSQL
  • pgvector
  • LangChain
  • CrewAI
  • Docker
Product tour

70%less manual job-fit research against the baseline it replaced

Every AI feature has a deterministic fallback, so the whole app still works with no API key.

07NLP classification pipeline · 2024GitHub

Fake News Detector

Problem

A claim spreads faster than the check on it, and the check usually arrives as a verdict with no working you can inspect.

What I built

An end to end NLP pipeline that classifies an article as fake or real, shipped twice over: a CLI predictor for batches and a Streamlit app for interactive use.

How it works

Text preprocessing and feature extraction, then training and evaluation against held out data, with error analysis feeding the next round of retraining.

The pieces
  • PreprocessingCleaning, tokenising and feature extraction over raw article text.
  • TrainingClassifier fitted and evaluated against held out data.
  • AnalysisError patterns reviewed to guide the next retraining pass.
  • DeliveryA CLI predictor and a Streamlit demo over the same model.
Why it is built this way

Shipping the model behind two interfaces rather than one is what made it usable: the CLI for volume, the app for the single article someone is actually arguing about.

  • Python
  • scikit-learn
  • NLTK
  • Streamlit

2interfaces over one model: a batch CLI and an interactive app

The same trained model answers a single pasted article and a whole file of them.

05 / Achievements

Wins &recognition.

Competition results, awards and grades.

  • M.S., CSULB

    4.0

    GPA, Information Systems (AI/ML)

    Graduate coursework in machine learning, data warehousing and analytics, alongside full time development work for the university.

  • Competition

    1st

    EDRAY shipment delay challenge

    Won with an XGBoost ensemble over 439,919 container movements across 82 ports: port availability delay predicted to within 1.36 days, and detention risk classified at 92 percent accuracy.

  • Production

    40%

    Less analyst time on recurring reports

    Institutional Research at CSULB, by moving accreditation and compliance reporting onto FastAPI services and automated ETL.

  • Certification

    Harvard

    E-Diploma in Business Analytics

    Harvard Business School Online: descriptive, predictive and prescriptive analysis for decision making.

  • B.Tech, RAIT

    9.42

    CGPA out of 10

    Electronics & Telecommunication with an AI specialisation.

  • Datathon

    LMU

    Wage gap study on a 24 year panel

    Fixed effects over roughly 170,000 NLSY97 job observations, with a salary history ban counterfactual.

  • Award

    Winner

    IETE–RAIT Winter Internship Program

    Selected build: an NLP summarisation service over PDFs, video and web pages.

  • Teaching

    100+

    Engineers trained in ML fundamentals

    Workshops and learning tracks as AI/ML facilitator at Google Developer Student Clubs.

  • Hackathon

    3rd

    KLEOS 2.0 Hackathon

    Third place out of more than 1,900 teams, from a 48 hour build.

  • Patent filed

    IN

    Antenna dimension prediction, Government of India

    A CNN that predicts antenna dimensions from electromagnetic simulation data, filed with the Indian Patent Office.

06 / Skills

Thestack.

0tools across 9 domains
  • 01

    AI & Machine Learning

    14
    • PyTorch
    • TensorFlow
    • scikit-learn
    • XGBoost
    • Transformers
    • BERT
    • LLMs
    • RAG
    • LangChain
    • CrewAI
    • Hugging Face
    • MLflow
    • Optuna
    • SHAP
  • 02

    Data Science & Statistics

    10
    • Pandas
    • NumPy
    • SciPy
    • Hypothesis testing
    • Regression
    • A/B testing
    • Forecasting
    • Clustering
    • Feature engineering
    • Cross validation
  • 03

    Data Engineering

    11
    • Spark
    • PySpark
    • Databricks
    • Delta Lake
    • Airflow
    • dbt
    • Kafka
    • Unity Catalog
    • ETL and ELT
    • Data modelling
    • Star schema
  • 04

    Databases

    12
    • PostgreSQL
    • Oracle
    • MySQL
    • Cloud SQL
    • Supabase
    • BigQuery
    • Snowflake
    • pgvector
    • Query optimisation
    • Indexing
    • Stored procedures
    • Alembic
  • 05

    Analytics & BI

    8
    • Tableau
    • Power BI
    • Looker
    • Google Analytics
    • Excel
    • SPSS
    • Alteryx
    • KPI design
  • 06

    Full Stack Development

    12
    • Next.js
    • React
    • React Native
    • TypeScript
    • FastAPI
    • Flask
    • Node.js
    • REST APIs
    • Microservices
    • OAuth and SSO
    • RBAC
    • Mapbox GL
  • 07

    Languages

    8
    • Python
    • SQL
    • JavaScript
    • TypeScript
    • Java
    • C++
    • R
    • Bash
  • 08

    Cloud & DevOps

    13
    • GCP
    • Cloud Run
    • Document AI
    • Vertex AI
    • AWS
    • Azure
    • Docker
    • Kubernetes
    • Terraform
    • GitLab CI/CD
    • GitHub Actions
    • pytest
    • Vercel
  • 09

    Product & Delivery

    11
    • Product roadmap
    • User research
    • PRDs and user stories
    • Backlog prioritisation
    • Agile and Scrum
    • Jira
    • Confluence
    • Figma
    • Stakeholder management
    • Risk management
    • Technical demos

08 / Contact

Let's buildsomething real.

I'm looking for AI/ML and software engineering, data engineering, analytics and data science, and technical product work. Based in Los Angeles, CA.